paper explaining why RL works over SFT or how in general works.
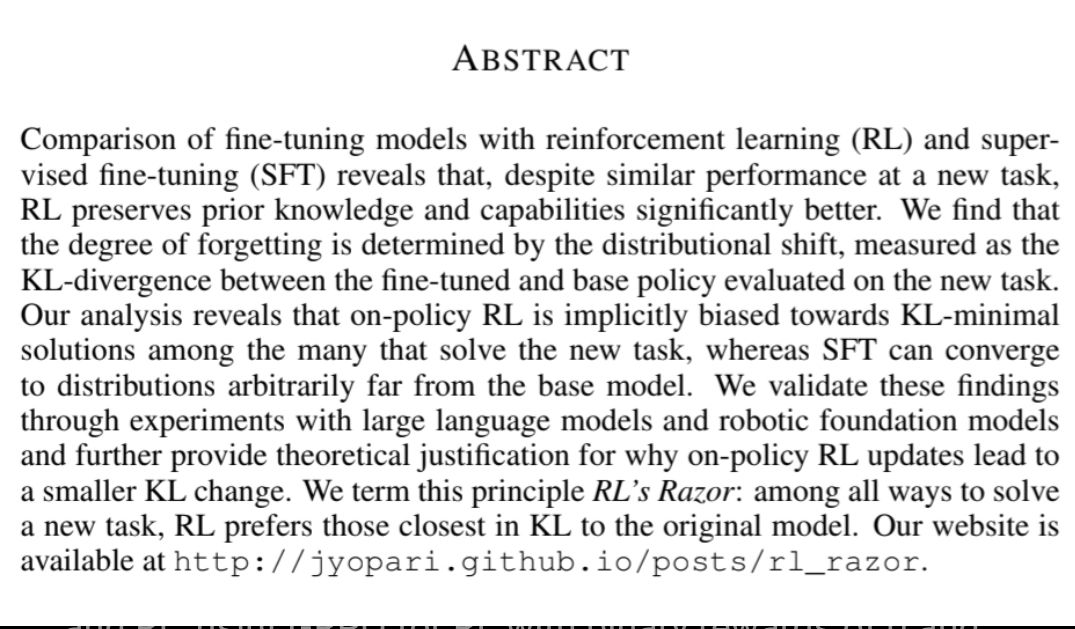
the main comparison is in terms of catastrophic forgetting and which one performs better.
setup
they use the same prompts for finetuning on both SFT and RL, usint GRPO for RL with binary rewards of 0 and 1 with no KL regularization.
then they trained various models with varying hyperparams and benched on old tasks (tasks not finetuned on) and new tasks.
oh they also tested on robotics lol
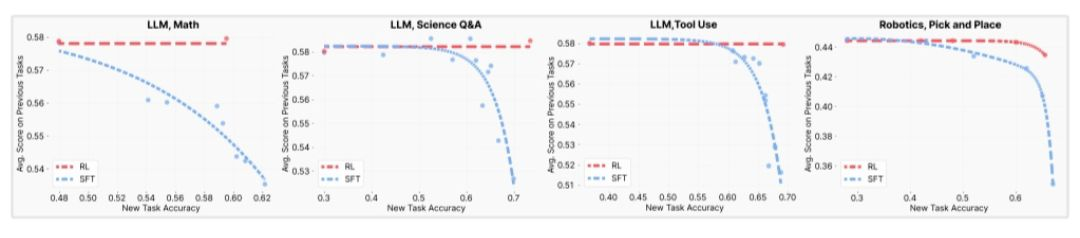 which well makes the case that RL is able to learn new tasks while incurrint minimal forgetting compared to SFT, it’s the pareto frontier.
explaination
finding the signal
what causes this?
they looked for a comparable consistent variable that would show objective difference causing this behavior apparently prev work state, magnitude weight changing, sparisty or gradient rank. they however find it to be KL div vs cross entropy to reliably explain the degree of forgetfullness.
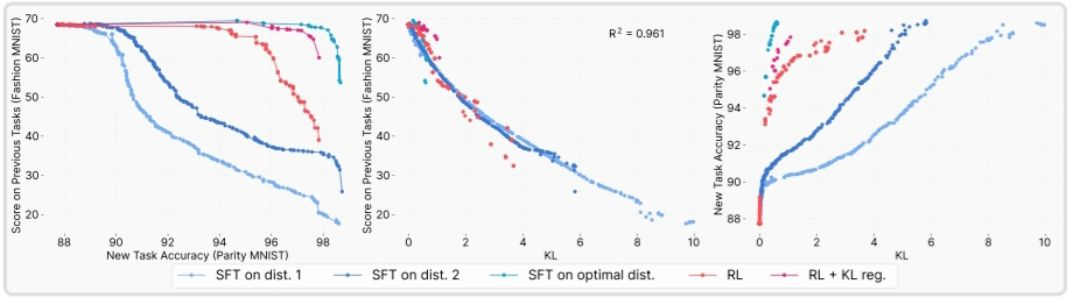 they tested this on Parsity MNIST since llms would be too expensive.
why did RL perform better?
they do various tests on onn policy offpolicy and pos neg examples
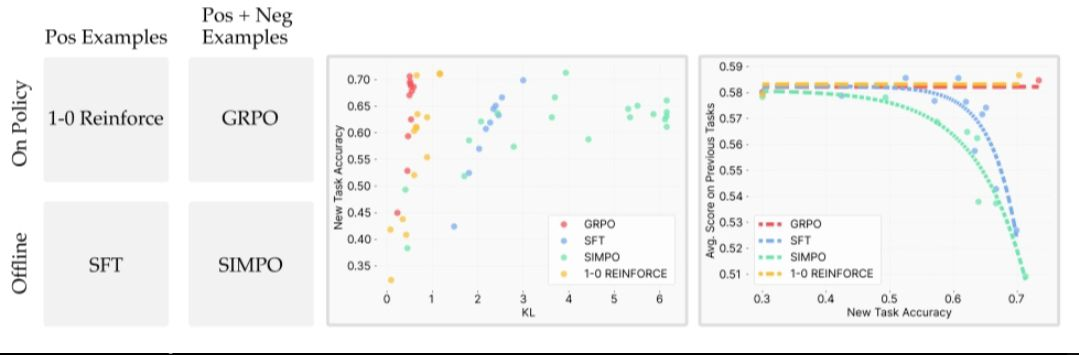 with reinforce , grpo, sft, simpo